


Part Number: AM68A
Hi,
I am currently deploying a custom BEVDet model that has been trained using QAT v2 on the AM68A development board. I am using the lowest-level C++ import tool (tidl_model_import.out) and compiling it by hand with a .txt configuration file.
The model has been exported as an onnx format, and the input is a .bin image in NV12 format.
According to the official documentation, the QAT model should bypass the advanced calibration function of PTQ and directly use the quantization parameters provided by the model itself.
- I would like to know if my configuration in .txt is correct:

- After my test, when numFramesBiasCalibration is set to 0, although the compilation was successful and the corresponding.bin and.out files were generated, the inference on the board failed. The error message at the board end is as follows:
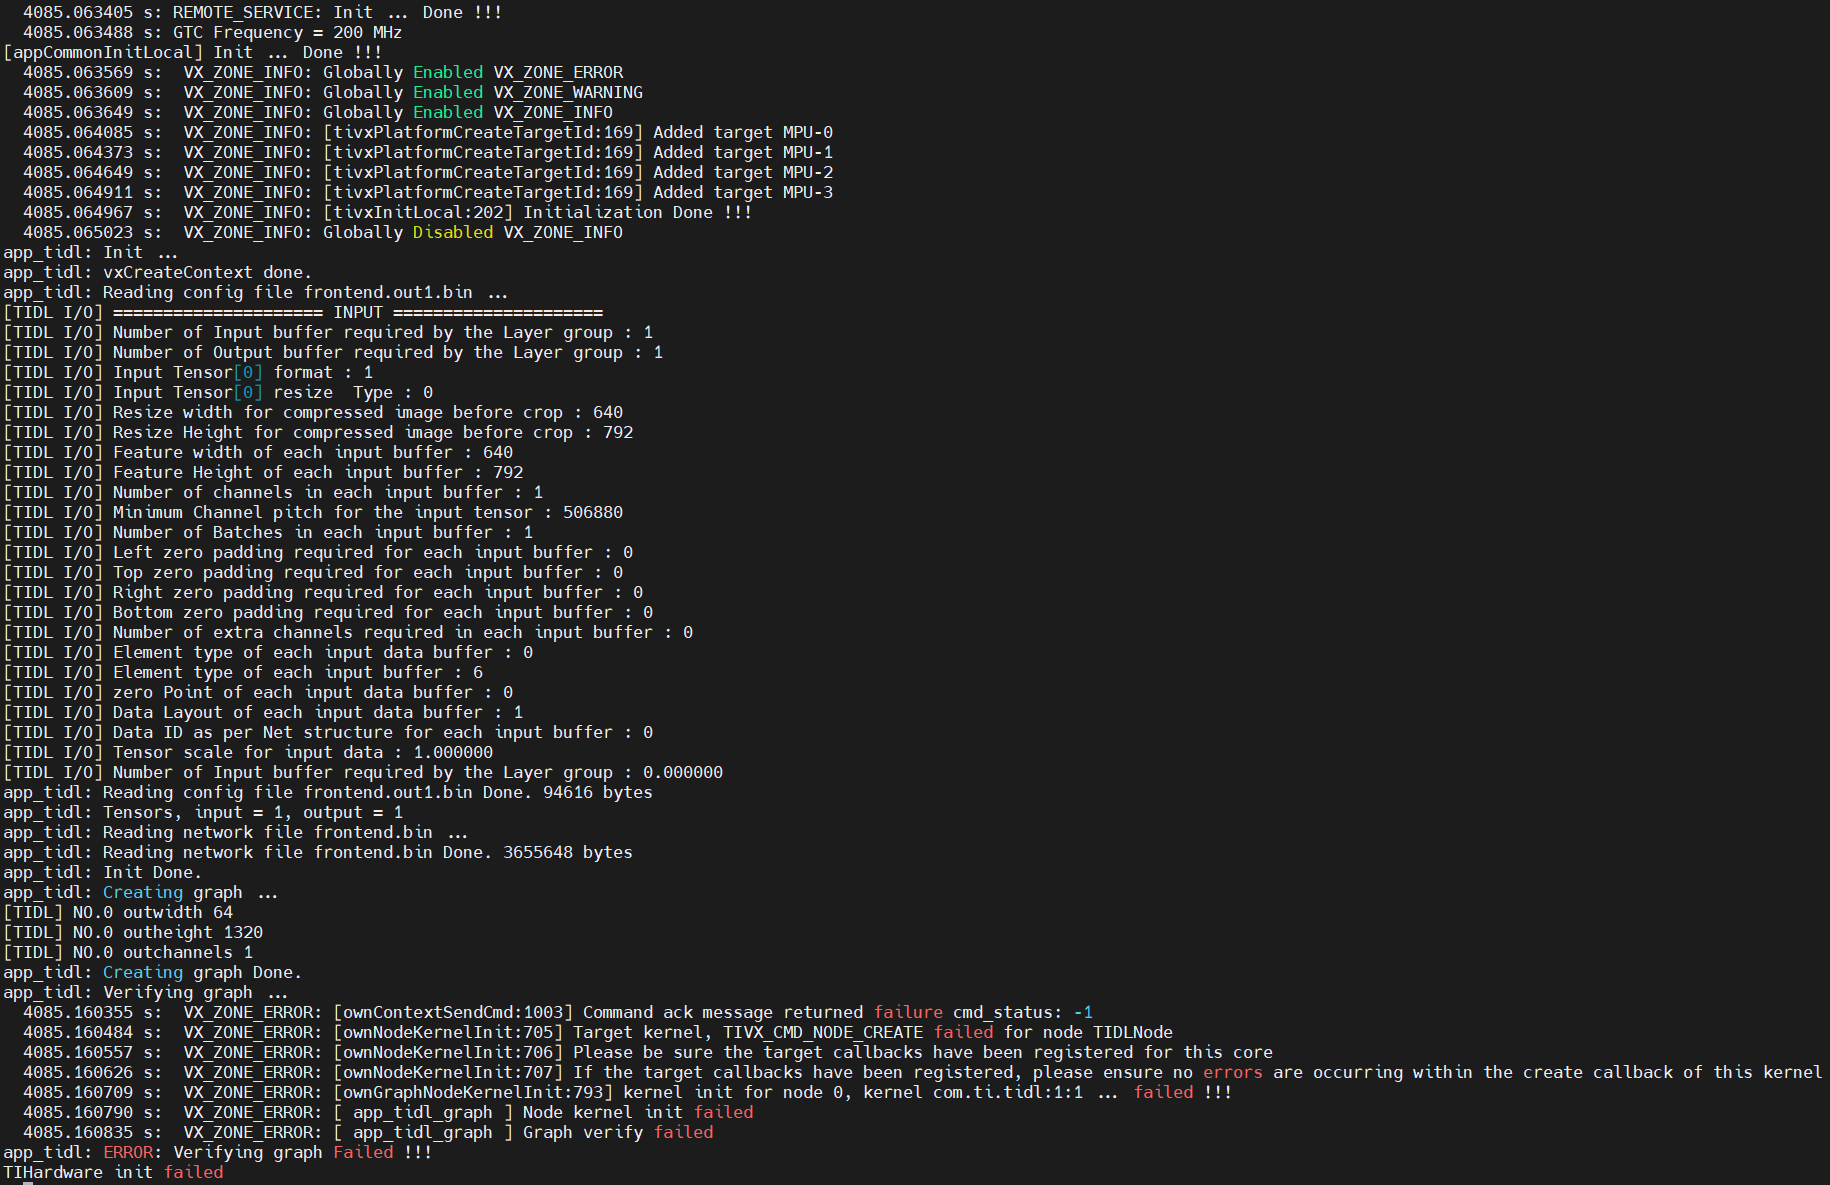
- Furthermore, when the value of inElementType is set to 6, the compilation is successful, but the board end still reports the same error. When the value of inElementType is set to 0, both compilation and reasoning proceed smoothly. However, the input of my ONNX model is indeed of type float32, and the inElementType should be set to 6.
- When numFramesBiasCalibration is set to 0, the compilation is successful, but the same error occurs in the inference package at the board end. When numFramesBiasCalibration is set to 1, both compilation and inference are successful, but the accuracy has significantly decreased. Was PTQ performed at this point?
Chip architecture: AM68A (J721S2)
SDK version: edgeai-tidl-tools-11_00_06_0
Compilation tool: tidl_model_import.out
Looking forward to your assistance.
